It’s been a few weeks since my last blog post; I am back in Chile, and there is a lot to discuss. But I’ll save you from the majority of it.
In September, I spent two weeks visiting Yale, which is a great place for astronomy. The department there is a good size, and there are always events to attend - talks, journal clubs, student/post-doc workshops, etc. This is pretty different from my previous experience at universities that had smaller departments. There is just a better sense of community once you get a department beyond some critical size.
The department also has a very positive attitude in regards to the academic culture. For me, the attitude of the community makes a world of difference. When I was a first-year graduate student I was surrounded by a lot of negativity. That continued into my second, and third year. It has taken me a very long time to work out of that. Having a more positive attitude about academia and astronomy gives me more motivation to keep working on things. It's a feeling I get when I attend astronomy meetings/conferences. And I’m pleased to report that I’m working on revising a paper that, hopefully, will get accepted for publication soon.
Also in the past month, I’ve had an undergraduate from UdeC emailing me requesting to work with me. I was hesitant at first, because I haven’t been sure where I would be in the near future. I decided to give him some reading, and now I am actually excited about giving him a project. We met in-person last week, and he said he wanted to work on some data. I think I have a mental sketch of a decent undergraduate project where he will get some experience and learn something useful. But now that I’ve taken him on as a student, it means more work and responsibility for me. This is all a good thing, because it means I continue to progress in my career.
I also had a conversation with my current faculty sponsor. We decided that it might make sense for me to apply to some faculty positions in order to help solve the Two-Body Problem. This is going to be very interesting; I’ve never applied to a faculty position before. After thinking about it for a couple days, I’ve convinced myself that I would make a good candidate, and I hope that my application(s) will reflect that.
For a while I have been pretty conflicted about how and where I might continue in my professional career. But since attending the data science workshop in August (a very positive experience) and since visiting Yale for another two weeks (another positive experience), I am a little less worried about where I may end up. I feel a renewed attitude, and I expect that whatever job/career opportunities arise will be rewarding.
Sunday, September 28, 2014

Monday, September 1, 2014
Data Science is Not Magic
We’re at the end of August and close to the end of the S2DS program that I’ve been attending in London. The program has been great, and I have learned much more in a month than I would have simply by investigating on my own. I have had a good team, and I feel like we accomplished something useful.
As I mentioned in previous posts, my team is focused on unifying offline shopping data (specifically from grocery stores) and online data from facebook. I won’t tell you the actual results that we found - for that you’ll have to sit in on our presentation on Tuesday afternoon. But, I will describe some of the methods that we’ve used.
We investigated whether users who were similar to one another in one data set could be recovered by looking at their habits in the other data set. This is referred to as a Look-Alike Engine. We went about it by creating similarity matrices that assign a score to each user-pair based on how similar they are to one another using the input data. For shopping habits that means comparing users who bought similar items. For the social network data that means comparing users who have liked similar content.
There are a couple of different metrics one can use to determine similarity between two sets. A simple metric is the Jaccard Index, defined as the number of items in common between two sets divided by the number of total items. We decided that this scoring metric was not producing the results that we wanted. If two users each have missing data, then they are scored as similar. This somewhat depends on how the data sets are constructed and how the code runs, but it can very easily count a ‘0’ in one user’s data as the same as a ‘0’ in another user’s data. We might not want that in the end.
Another metric is the ‘cosine’ similarity score. This requires one to vectorize the data in a consistent way, because the cosine metric is defined as the dot product of the two user’s data normalized by the product of the magnitudes. Recall that the dot product can be written: A dot B = A*B*cosine(theta). So this method simply calculates the value of cosine(theta). At first I found this concept to be slightly difficult to apply to “shopping habits” and “likes” from facebook. However, it is fairly straightforward once you organize the data into a vector.
For example, with the movie ‘likes’ from facebook, we created an array/vector where every element is a possible movie title. We populated the array/vector with a value of 1 if the user ‘likes’ the title, or a zero if the user has not ‘liked’ that title. Then we had an array with all possible dimensions (movie titles) for every user. The cosine metric is simply the dot product of the arrays. For our data this meant that if two users did not declare a ‘like’ for a given movie, then they would not be considered similar - we don’t actually know if they liked the movie or if they didn’t like it. Not declaring a preference is not the same as dis-liking a thing.
Once we measured the similarity between users with a given metric, we organized the data into a large similarity matrix. This matrix simply contained all the similarity scores for every user pair, and allowed us to find the users who are most similar to one another.
Finally, we could test whether or not users who were similar in one data set were also similar in another. We selected the most similar users in one set to use as a control sample. Then in the other set we selected the most similar users and compared the two resulting selections of users to see how many we recalled and to what precision.
Recall and precision are two metrics by which we measured the ability of our method to find similar users. Recall is defined as the number of true positives in the set divided by the total number we could possibly find (the true positives plus false negatives). Precision is defined as the number of true positives divided by the number you’ve actually selected (true positives plus false positives). Depending on your application you might want to sacrifice some precision in order to obtain better recall, or vice versa.
Lastly, in order to determine if our method was actually any good, we conducted a simple monte-carlo simulation where we randomly selected users from the experimental data set to compare to the control set. In the end, we were able to determine the recall and precision for random selections and for our selections using the similarity scores as a function of the number of users in the sample selection.
Now if there actually is a correlation between people’s shopping habits and the movies and TV shows that they like on facebook, then we expect to more accurately select users from our similarity matrix than we would just by selecting at random. As I said, I won’t tell you the result, but you can hazard a guess on your own.
Coming up we will present our results to other participants and partner companies on Tuesday afternoon. Then on Wednesday afternoon there will be a job fair where will will be able to discuss opportunities with the partner companies.
As I said, I have found this experience very useful, and now I have a definite project that I can point to - with results - that shows what I can do as a data scientist. I am hoping that I will be able to develop more skills in data science and machine learning techniques as I move forward with my career.
Kyle D Hiner
Saturday, August 16, 2014
S2DS and python, etc. - Pt 2
Week 2 of S2DS is down, and this week we began working full-time on our projects. As I mentioned before, my team has some proprietary data to work with. We’ll be combining offline shopping habits with online social network preferences to try to build models about consumer demographics and behaviors. As of now we’ve just been looking at the data to get a feel for what is in there, and we’ve started to brainstorm some ideas about what we can do with them.
Our team only has three members. One is working with the offline data, while I have partnered with the other to work with our Facebook data. We are currently using a python package called GraphLab to do some modeling and analysis of the data. To begin, we wanted to see if we could create a movie recommendation engine based on the movies that users had ‘liked’ on their Facebook profiles.
The GraphLab tool makes implementing machine learning techniques so stream-lined and black-boxed that it is almost trivial. Almost. And, actually, as a scientist, that is extraordinarily frustrating. I’m dying to get into the details about the algorithms and theory behind this stuff. That, as you might expect, is non-trivial. At a basic level, you don’t need to know all that stuff, but if you want to understand what is going on and how best to use the tools, you had better know it. As a scientist I can’t stand using a tool if I don’t know how it works. I can’t defend my work if I don’t know what it is that I actually did - that is fundamental to science. The good news is that everyone here understands that.
The bad news is that I still only get a couple weeks to dive into all of it. It turns out that industry/business works on a much shorter timescales than academia. That’s what we are told, at least. For now, I am trying to learn as much as possible. But, as with any new endeavor, you can only learn so much in a short amount of time. I know I won’t be an expert after this program, but I will have a great deal more knowledge. (Aside: One thing I learned from working in the CA Senate - if you know one thing about anything that no one else knows, then you are the expert in the room.)
I’ve been getting more comfortable with programming in python now. After taking the Udacity courses and playing around on my own, I feel like I can understand many of the basic structures that python is using. Even though I don’t know a lot right now, I am more confident in my ability to quickly learn python and its various packages (pandas, numpy, scipy, graphlab, etc.) now that I have more experience with them - and that is going to be really important going forward in my career.
At the end of this week, we (my S2DS team and I) have created a basic recommendation function for movies based on people’s Facebook likes. Almost immediately I’ve learned a good lesson about testing code. As I mentioned above, we are using a python package that works a lot like a black-box. So, to figure out how it works, we have to test various inputs and see if their output makes sense. For example, we’ve tried generating fake users that are copies of our real users to see if we get consistent recommendations for the invented data. At first, we didn’t, which indicated we were doing something wrong. So, the value of testing code is very high. Our background in science has given us this attention to systematics and details, so that we understand what it is exactly that we are doing, and we can produce consistent results.
We are planning to expand on our work by increasing complexity. We would like to incorporate other variables like music and book preferences as well. Hopefully we’ll be able to take in a given set of music preferences and recommend both additional music and movies based on other users’ preferences. Collectively this is sometimes referred to as a look-alike algorithm.
A lot of the work that I’ve just described is just exploratory. Next week we are going to have to focus some more on combining our data sets and doing some real hypothesis testing. In the end, we are hoping to develop an/some algorithm(s) that will actually be useful. I think I will be a very strong candidate for data science jobs by the end of the program.
Kyle D Hiner
Studious data scientist
Sunday, August 10, 2014
Science to Data Science, Pt 1
I’ve traveled to London for a 5-week program on data science techniques. The program is called S2DS (Science to Data Science), and so far it has been really great. There are about 80 participants, who are divided into small (~4 person) teams. Each team partners with a company for the month in order to complete a project that is relevant to the business and serves to teach the participant valuable data science techniques. I actually have an some open questions regarding intellectual property, but glossing over that . . .
We’ve just completed the first week, and we’ve covered a lot of material. It is going pretty fast, and I feel like I’ve been here a while already even though I still haven’t met all of the participants. The lectures have been rather superficial. One simply cannot realistically give an substantial introduction into any of these topics in the small time frames that we have. You can’t learn python in 2 hours, similar for Hadoop, SQL, and machine learning. That said, the introductory lectures are valuable. I am still trying to grasp all the concepts, but hopefully I will get much a more detailed experience as the program progresses.
The thing I am most excited about in this program is expanding my skill set. I’ve always been somewhat uncomfortable with my level of competency with various tasks and programming. I’ve previously written about trying to learn more python, including through the Udacity online coursework. This workshop will really be a time that I can dive into some new things that are applicable both in and outside of astronomy.
So far we have had lectures on good coding practices, Hadoop, Database introduction, SQL, NoSQL, statistics, R, natural language processing, machine learning techniques, and even some more business oriented seminars on economics and marketing. Meanwhile, we’ve also met with our project mentors to outline the project scope for our group work over the next few weeks. I am most excited to dive deeper into the machine learning techniques, because I feel like those are most useful across a wide variety of potential future jobs.
For my team’s project, we’ll be doing a lot of machine learning and trying to do some predictive analysis. The data set that we are getting access to is proprietary, so I’m not allowed to share information about it. But, generally, we’ll be working with customer data to predict purchasing habits and/or demographics of the customer. It is kind of crazy to think about the amount of information people are willingly (or unwittingly) handing over to various companies. Regardless, I am looking forward to learning the techniques of the project and potentially applying them in academia or other industries.
Kyle D Hiner
Data scientist?
Sunday, July 27, 2014
Tostada Granos y Bliss
Here is my first post about one of my most rewarding hobbies: coffee roasting.
I started drinking coffee in college. I tried coffee as a teenager, but never really liked the stuff that my parents would buy from the store. Mostly this was your regular low quality brand. Sometimes they would buy Kona blends, and almost always they bought decaf. A lot of people like Kona, but I don’t, and it wasn’t until much later that I developed a taste for other coffees.
Because I had never really enjoyed coffee, I mostly stuck with mocha drinks if I went to coffee shops with friends. But, somewhere along the way I switched to just drinking regular black coffee. The more I payed attention to it, the more I enjoyed it. I think that is part of why I enjoy it - to fully appreciate coffee it takes time, patience, and focus.
A few years ago I started roasting my own coffee at home. I found an online store that fortunately had a physical store-front in my city. That store actually specialized in home-brew beer kits, but they also sold coffee for home roasting. I purchased their introductory kit online, and went to the store to get some green coffee beans.
The roasting kit is actually very simple. It is a stove-top whirly pop popcorn maker and a thermometer. That’s it. I punched a hole in the top of the popcorn maker with a corkscrew so I could insert the thermometer. The thermometer itself is actually pretty special - it goes up to 500 F. I’ve never seen one in a store, although they must exist. If you look for a thermometer like this you will probably find candy thermometers, but that isn’t what this is. This one is thin and more like a meat thermometer that goes up to 500 F. It’s actually quite important for the process.
Anyways, I ended up getting some green coffee beans from that store and I dumped them into the popcorn popper pot and started roasting. The first thing I noticed was steam! Lots of steam! And then smoke! Lots of smoke! and then chaff! Lots of chaff! It was a bit of a mess. And it was delicious. The aroma of freshly roasted coffee is intoxicating.
Since I started roasting my own coffee I have learned a lot more about what goes into a good cup. I bought a book and started reading it; although I still haven’t actually finished it. I may write more about coffee roasting in the future, including my dreams for running my own café, but this time I just wanted to say . . .
I miss coffee roasting!!!!
Since living in Chile, I haven’t been able to roast my own coffee. That’s mostly because I don’t know anyone who sells green coffee beans. There is one decent coffee roaster here in Concepcion, and he wouldn’t sell me green beans. I was/am very disappointed. There are many things I miss about the US, and coffee roasting is probably number 3 on the list (the first two being a person and a cat).
You can probably already tell that I enjoy coffee from my chosen background image for this blog. Although, I have to say that that is a sorry-looking batch of roasted coffee. My coffee comes out much more evenly. You can see in the background image that some beans are barely roasted at all, while others are charred. tsk tsk.
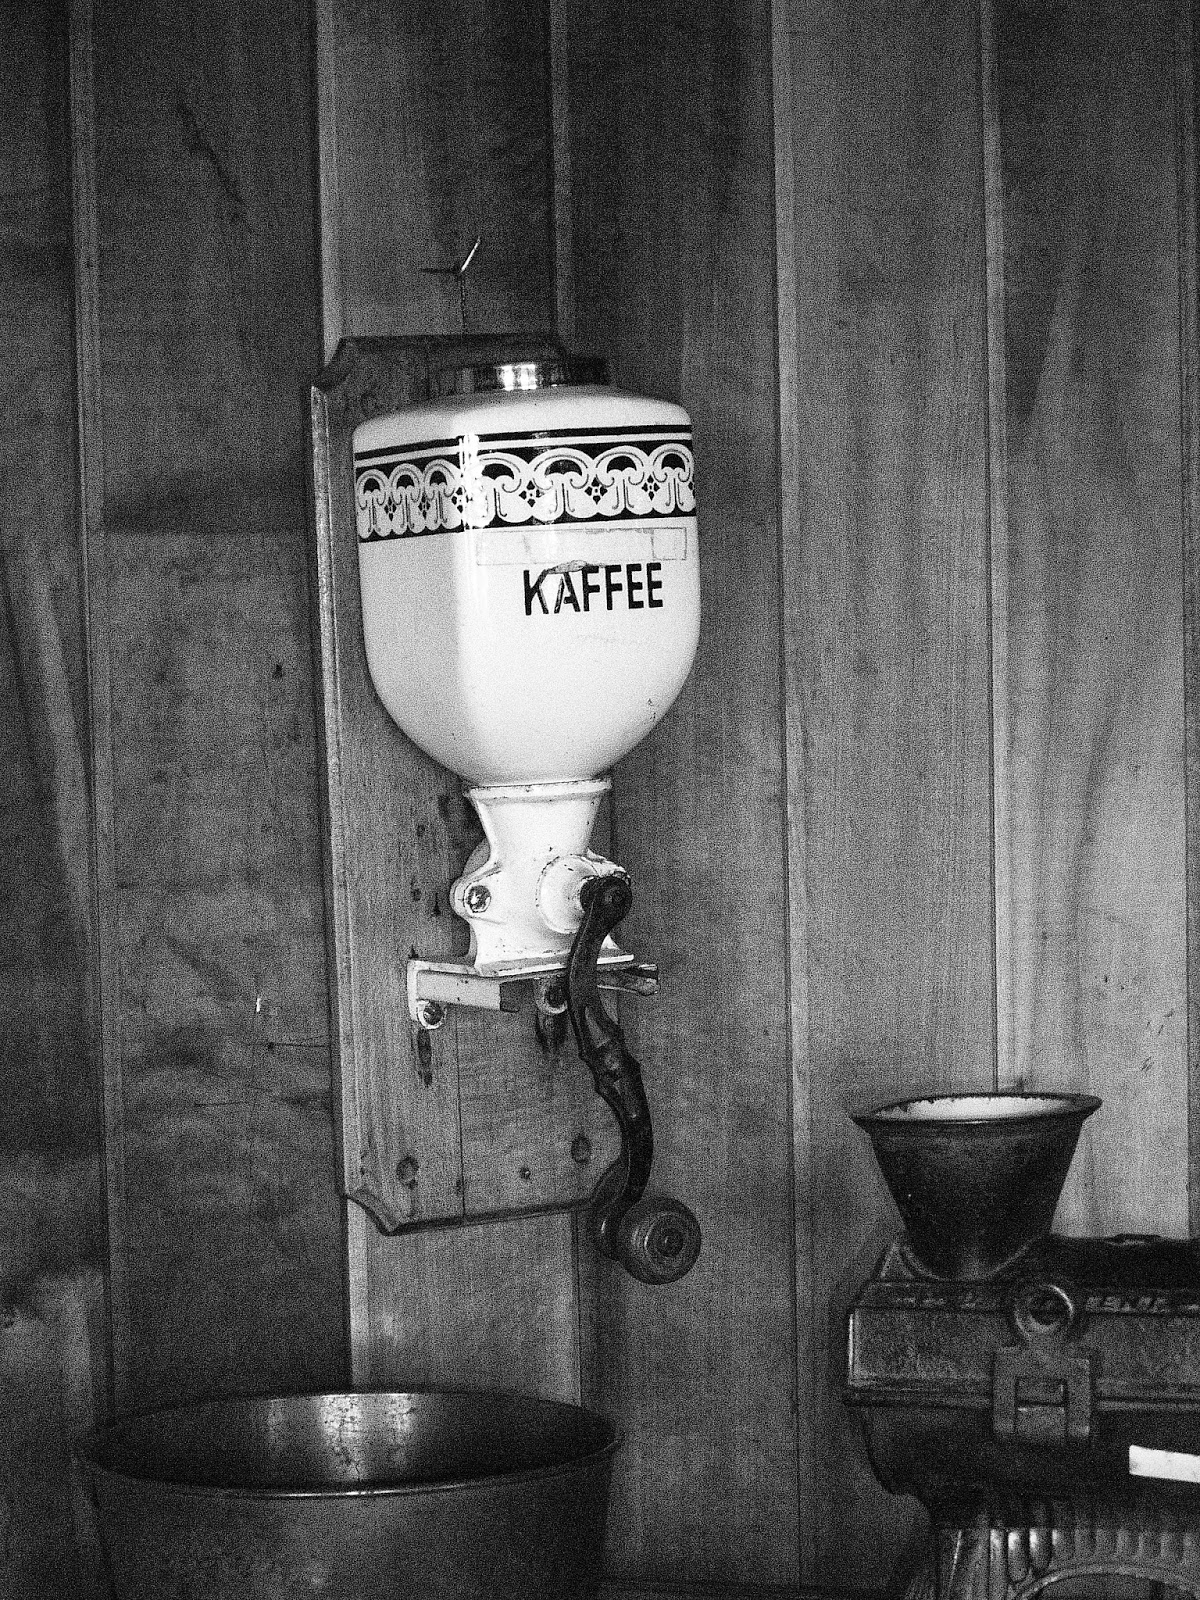
I’ve included an image of some coffee that I roasted a long time ago (and subsequently ground up, soaked in hot water, and drank to my delight). Le sigh. I miss good coffee. Also, I am including an image of an antique coffee grinder that I saw in an historical German house outside the town of Frutillar in the south of Chile. Both are original photos, so . . . copyright me?
Until next time, chao!
Kyle D Hiner
Coffee-Roaster Extraordinaire

I started drinking coffee in college. I tried coffee as a teenager, but never really liked the stuff that my parents would buy from the store. Mostly this was your regular low quality brand. Sometimes they would buy Kona blends, and almost always they bought decaf. A lot of people like Kona, but I don’t, and it wasn’t until much later that I developed a taste for other coffees.
Because I had never really enjoyed coffee, I mostly stuck with mocha drinks if I went to coffee shops with friends. But, somewhere along the way I switched to just drinking regular black coffee. The more I payed attention to it, the more I enjoyed it. I think that is part of why I enjoy it - to fully appreciate coffee it takes time, patience, and focus.
A few years ago I started roasting my own coffee at home. I found an online store that fortunately had a physical store-front in my city. That store actually specialized in home-brew beer kits, but they also sold coffee for home roasting. I purchased their introductory kit online, and went to the store to get some green coffee beans.
The roasting kit is actually very simple. It is a stove-top whirly pop popcorn maker and a thermometer. That’s it. I punched a hole in the top of the popcorn maker with a corkscrew so I could insert the thermometer. The thermometer itself is actually pretty special - it goes up to 500 F. I’ve never seen one in a store, although they must exist. If you look for a thermometer like this you will probably find candy thermometers, but that isn’t what this is. This one is thin and more like a meat thermometer that goes up to 500 F. It’s actually quite important for the process.
Anyways, I ended up getting some green coffee beans from that store and I dumped them into the popcorn popper pot and started roasting. The first thing I noticed was steam! Lots of steam! And then smoke! Lots of smoke! and then chaff! Lots of chaff! It was a bit of a mess. And it was delicious. The aroma of freshly roasted coffee is intoxicating.
Since I started roasting my own coffee I have learned a lot more about what goes into a good cup. I bought a book and started reading it; although I still haven’t actually finished it. I may write more about coffee roasting in the future, including my dreams for running my own café, but this time I just wanted to say . . .
I miss coffee roasting!!!!
Since living in Chile, I haven’t been able to roast my own coffee. That’s mostly because I don’t know anyone who sells green coffee beans. There is one decent coffee roaster here in Concepcion, and he wouldn’t sell me green beans. I was/am very disappointed. There are many things I miss about the US, and coffee roasting is probably number 3 on the list (the first two being a person and a cat).
You can probably already tell that I enjoy coffee from my chosen background image for this blog. Although, I have to say that that is a sorry-looking batch of roasted coffee. My coffee comes out much more evenly. You can see in the background image that some beans are barely roasted at all, while others are charred. tsk tsk.
I’ve included an image of some coffee that I roasted a long time ago (and subsequently ground up, soaked in hot water, and drank to my delight). Le sigh. I miss good coffee. Also, I am including an image of an antique coffee grinder that I saw in an historical German house outside the town of Frutillar in the south of Chile. Both are original photos, so . . . copyright me?
Until next time, chao!
Kyle D Hiner
Coffee-Roaster Extraordinaire
Tuesday, July 22, 2014
Proposaling!
Foreword: I actually wrote this post a few months ago while I was working on some proposals for telescope time. Also, yes, I was thinking of starting a blog a few months ago, but didn't commit to it until recently.
Proposals are an interesting beast. In astronomy, the proposals for funding and those for data are typically decoupled. In some cases (e.g., when apply for Hubble Space Telescope), support funding comes with the granted time for data acquisition. These applications are rare, and highly sought after.
I have a fellowship sponsored by the Chilean national government. This fellowship pays my salary and some other costs such as travel and publication costs associated with doing science. However, there is no guarantee that I will actually get time on telescopes in order to collect the data necessary for the project that the fellowship is intended to fund! Thus, in addition to the initial fellowship proposal, I have to write many observing proposals in order to get data. One would think that I am decently good at it by now.
In my experience, every proposal is a snarling jabberwocky that needs to be wrestled and tamed until it fits in a cage of predetermined size and material.
These times are often great for learning a lot about my science, as they require some level of reading. I need to know what I’m talking about right? They are also exciting times, because I think a lot about the projects that I am doing or want to do. But my main point for this post is this:
The amount of time you invest in a proposal needs to be carefully considered. I know people who work to the very last minute on proposals. The idea here is that every change you think of can only make the proposal better, and if that one change makes it good enough to get time, then it is worth making. But I think a little bit differently . . . in part, because that method leads to tremendous amounts of stress, late hours, and sweating bullets trying to get the proposal submitted in the last 10 minutes before the deadline and oh my god, did the website crash or is it just my internet - freak out! I have a typo!
No. Here’s the way I look at it:
The “goodness” of a proposal is a function of the amount of time/effort one spends on it. However, that function is not a power-law, not a quadratic function, not even linear. That function quickly closes in on an asymptote (see figure). And no matter how much you work on that proposal it’s never going above that asymptote. Now, somewhere on the “goodness” scale is a cut-off for how good your proposal has to be in order to be granted time, and many factors go into determining that critical value. As long as your proposal reaches that level, then it is “good enough” - you get the time, you get the data, you go on with your life. And it may in fact be that no matter how much time and effort you dump into your proposal, it will never meet that critical value.
Furthermore, it is nearly impossible to predict what that value is. You’ll go insane if you try to squeeze every last moment into proposaling. So, try not to go down the path of infinite time/effort. At some point there is nothing more you can do to make your proposal get time.
At least that’s what I try to do. Inevitably, I get sucked into the vortex of proposal deadlines.

Figure: Blue - your proposal "goodness". Green - the maximum "goodness" your proposal will ever have (determined by quality of proposed science). Red - critical value at which your proposal will make it past review and be granted time (determined by your writing ability and the mood of the review committee).
Kyle D Hiner
More blogs to come
Epilogue: Since the writing of that initial post I've found out the results of the applications I had submitted. One of my proposals was successful, while two others were denied time. I could probably do an analysis to see if I actually beat the odds, but that would require me doing some more research than I really care to do at this point. In any case, I (and my research group) was granted 3 nights of observing with the Magellan telescope at Las Campanas Observatory, Chile. That's a big deal. Each night costs about $30k to run the telescope. Effectively, I was given ~$90k to do some research. There's more to say on that topic, but this post is long enough already.
Proposals are an interesting beast. In astronomy, the proposals for funding and those for data are typically decoupled. In some cases (e.g., when apply for Hubble Space Telescope), support funding comes with the granted time for data acquisition. These applications are rare, and highly sought after.
I have a fellowship sponsored by the Chilean national government. This fellowship pays my salary and some other costs such as travel and publication costs associated with doing science. However, there is no guarantee that I will actually get time on telescopes in order to collect the data necessary for the project that the fellowship is intended to fund! Thus, in addition to the initial fellowship proposal, I have to write many observing proposals in order to get data. One would think that I am decently good at it by now.
In my experience, every proposal is a snarling jabberwocky that needs to be wrestled and tamed until it fits in a cage of predetermined size and material.
These times are often great for learning a lot about my science, as they require some level of reading. I need to know what I’m talking about right? They are also exciting times, because I think a lot about the projects that I am doing or want to do. But my main point for this post is this:
The amount of time you invest in a proposal needs to be carefully considered. I know people who work to the very last minute on proposals. The idea here is that every change you think of can only make the proposal better, and if that one change makes it good enough to get time, then it is worth making. But I think a little bit differently . . . in part, because that method leads to tremendous amounts of stress, late hours, and sweating bullets trying to get the proposal submitted in the last 10 minutes before the deadline and oh my god, did the website crash or is it just my internet - freak out! I have a typo!
No. Here’s the way I look at it:
The “goodness” of a proposal is a function of the amount of time/effort one spends on it. However, that function is not a power-law, not a quadratic function, not even linear. That function quickly closes in on an asymptote (see figure). And no matter how much you work on that proposal it’s never going above that asymptote. Now, somewhere on the “goodness” scale is a cut-off for how good your proposal has to be in order to be granted time, and many factors go into determining that critical value. As long as your proposal reaches that level, then it is “good enough” - you get the time, you get the data, you go on with your life. And it may in fact be that no matter how much time and effort you dump into your proposal, it will never meet that critical value.
Furthermore, it is nearly impossible to predict what that value is. You’ll go insane if you try to squeeze every last moment into proposaling. So, try not to go down the path of infinite time/effort. At some point there is nothing more you can do to make your proposal get time.
At least that’s what I try to do. Inevitably, I get sucked into the vortex of proposal deadlines.
Figure: Blue - your proposal "goodness". Green - the maximum "goodness" your proposal will ever have (determined by quality of proposed science). Red - critical value at which your proposal will make it past review and be granted time (determined by your writing ability and the mood of the review committee).
Kyle D Hiner
More blogs to come
Epilogue: Since the writing of that initial post I've found out the results of the applications I had submitted. One of my proposals was successful, while two others were denied time. I could probably do an analysis to see if I actually beat the odds, but that would require me doing some more research than I really care to do at this point. In any case, I (and my research group) was granted 3 nights of observing with the Magellan telescope at Las Campanas Observatory, Chile. That's a big deal. Each night costs about $30k to run the telescope. Effectively, I was given ~$90k to do some research. There's more to say on that topic, but this post is long enough already.
Thursday, July 17, 2014
Astro-Reports: The Teacup AGN
Recently I read an article regarding the “Teacup AGN”, so named because of its apparent shape in visual images. Although, if you ask me, it doesn’t look much like a teacup, even if it does have a loop.
This is a very interesting case that is reminiscent of Hanny’s Voorwerp galaxy. Both cases exhibit extended emission line regions, which are very large swaths of gas that are ionized. Ionization occurs when diffuse gas is illuminated by very energetic photons. The “ionizing photons” interact with the gas, give energy to electrons, and kick the electrons off of their atoms. Subsequently, an electron freed in this manner occasionally falls back down onto an atom. When it does so, it gives off energy by emitting another photon. These are the photons that we see when we observe the gas.
If you take a spectrum of the gas, you’ll be able to identify discrete bright spots - what we call emission lines. Some of those emission lines show up stronger than others. This is the result of various physical conditions such as the density of the gas, and the light that is causing it to be ionized. What that means is that if you observe the emission line intensities and their ratios, you can infer things about the ionizing source. In the Teacup AGN, that ionizing source is an active galactic nucleus. I can write more about them later.
In the paper I read recently, the investigators (Gagne, et al.) measured the spectrum at discrete locations along the extended emission line region (the ionized gas). Then, they predicted properties of the ionizing source based on all those individual data points. Specifically, they calculated the luminosity (or brightness) of the active nucleus that would be needed to create all the emission line strengths and ratios that they observed at the specific locations in the galaxy. And because light has a finite travel speed, this allowed them to track the luminosity of the source over time.
By analogy, the analysis worked, because each spot in the gas acted like a photograph of the active nucleus. The "photographs" from the outer edges of the galaxy showed a very bright source and those from the inner regions showed a dim source. Because the "photos" from the inner region are more recent than those from the outer regions, it can be inferred that the active nucleus dimmed over that time period.
The authors’ main result is that the illuminating source decreased its brightness by a factor of 100 over the course of 46,000 years. That is not that long relative to the lifetime of stars and galaxies. The result, suggests that active nuclei can turn on and off rather quickly.
Kyle D Hiner
Learning tocrawl blog.
This is a very interesting case that is reminiscent of Hanny’s Voorwerp galaxy. Both cases exhibit extended emission line regions, which are very large swaths of gas that are ionized. Ionization occurs when diffuse gas is illuminated by very energetic photons. The “ionizing photons” interact with the gas, give energy to electrons, and kick the electrons off of their atoms. Subsequently, an electron freed in this manner occasionally falls back down onto an atom. When it does so, it gives off energy by emitting another photon. These are the photons that we see when we observe the gas.
If you take a spectrum of the gas, you’ll be able to identify discrete bright spots - what we call emission lines. Some of those emission lines show up stronger than others. This is the result of various physical conditions such as the density of the gas, and the light that is causing it to be ionized. What that means is that if you observe the emission line intensities and their ratios, you can infer things about the ionizing source. In the Teacup AGN, that ionizing source is an active galactic nucleus. I can write more about them later.
In the paper I read recently, the investigators (Gagne, et al.) measured the spectrum at discrete locations along the extended emission line region (the ionized gas). Then, they predicted properties of the ionizing source based on all those individual data points. Specifically, they calculated the luminosity (or brightness) of the active nucleus that would be needed to create all the emission line strengths and ratios that they observed at the specific locations in the galaxy. And because light has a finite travel speed, this allowed them to track the luminosity of the source over time.
By analogy, the analysis worked, because each spot in the gas acted like a photograph of the active nucleus. The "photographs" from the outer edges of the galaxy showed a very bright source and those from the inner regions showed a dim source. Because the "photos" from the inner region are more recent than those from the outer regions, it can be inferred that the active nucleus dimmed over that time period.
The authors’ main result is that the illuminating source decreased its brightness by a factor of 100 over the course of 46,000 years. That is not that long relative to the lifetime of stars and galaxies. The result, suggests that active nuclei can turn on and off rather quickly.
Kyle D Hiner
Learning to
Subscribe to:
Posts (Atom)